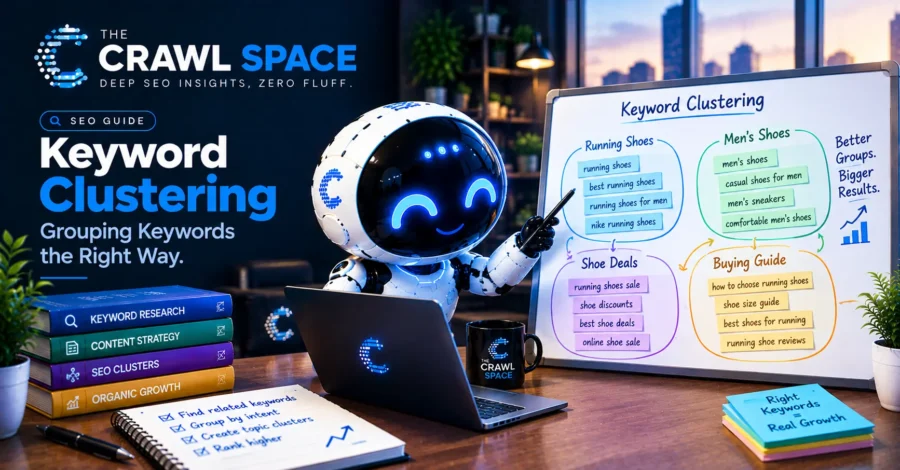
Keyword clustering is the process of grouping related keywords that share the same underlying search intent, so that each group can be addressed by a single, comprehensive page instead of split across several competing ones. This article is part of the What Is Keyword Research? guide.
Why Cluster Instead of One Page Per Keyword
Building a separate page for every keyword a research process turns up produces exactly the outcome Keyword Cannibalization describes: multiple pages competing against each other for the same intent instead of one page concentrating all the relevant ranking signals. Clustering exists specifically to prevent that — identifying, before any content gets written, which keywords genuinely belong together on the same page.
The Real Test: SERP Overlap, Not Word Similarity
The most reliable way to tell whether two keywords actually belong in the same cluster isn’t how similar the words look — it’s whether Google is already treating them as the same topic. Search each candidate keyword and compare the top-10 results: when a meaningful share of the same URLs show up for both searches, Google has effectively already told you they serve the same underlying intent, and they belong on the same page. When the results barely overlap, that’s a signal the two terms serve genuinely different intents, even if the phrases look closely related on paper.
This matters because word similarity alone is an unreliable guide in both directions. Two phrases can look different but mean essentially the same thing to a searcher, and two phrases can look nearly identical while serving completely different intents.
For a smaller keyword set, this can be done manually: search each term in a private browser window, record the top 10 results, and compare. For larger lists, this is what dedicated clustering tools automate, using the same underlying logic at scale.
The Intent Trap: Similar Topic, Different Intent
A commonly cited example makes this concrete: “what is content marketing” and “content marketing agency” both relate to the same broad topic, but they serve entirely different searchers. One is informational — someone learning a concept. The other is transactional — someone looking to hire. Their top-10 results would look almost nothing alike, correctly signaling that these two terms should never share a page, no matter how related the underlying topic seems. Checking SERP overlap catches this automatically; judging by topic alone would not.
→ For the broader intent framework this fits into: Search Intent in the main SEO guide
Structuring a Cluster: One Primary Keyword, Several Secondary Ones
Once a cluster is confirmed, it typically gets organized around a single primary keyword — usually the highest-volume or most commercially relevant term in the group — with the other confirmed cluster members treated as secondary keywords the page should also naturally address. These secondary terms don’t need to be forced into the text; a page that genuinely and thoroughly covers the topic tends to satisfy them without deliberate effort, the same principle already covered in how long-tail keywords get handled within a cluster.
Handling Orphan Keywords
Not every keyword fits neatly into a cluster. A term that doesn’t share meaningful SERP overlap with anything else in the research set is an orphan — rather than forcing it into an unrelated cluster or building a thin standalone page just for it, orphan keywords are usually better handled by folding them into supporting content within an existing page (an FAQ entry, a subheading) or treating them as a genuinely separate topic worth its own future research rather than an immediate page.
Common Mistakes
- Clustering by exact-match word similarity instead of checking actual SERP overlap, misgrouping terms that only look related
- Ignoring intent differences within a topic, merging informational and transactional keywords onto the same page when they need separate treatment
- Forcing every keyword into a cluster, rather than recognizing genuine orphans that need different handling
- Building a cluster too large to address on one page, which usually signals it should be split into more focused sub-clusters instead
Frequently Asked Questions
How much SERP overlap counts as “enough” to cluster two keywords together?
There’s no single universal threshold — different tools and practitioners use varying cutoffs, and the exact number matters less than the underlying principle: substantial, consistent overlap signals shared intent, while minimal overlap signals separate intents.
Can keyword clustering be done without a paid tool?
Yes, for smaller keyword sets — manually comparing top-10 results for each term works, just more slowly than an automated tool. It’s genuinely useful to do this manually at least once to build an intuitive sense of how the logic works before relying on automation for larger lists.
What happens if I skip clustering entirely?
Skipping it doesn’t eliminate the underlying relationships between keywords — it just means they surface later as unintentional competition between pages, which is harder and more disruptive to fix after content already exists than to plan around from the start.
The Bottom Line
Keyword clustering groups keywords by verified shared intent — measured through actual SERP overlap, not surface-level word similarity — so that one comprehensive page can serve a whole cluster instead of several thinner pages competing against each other. Getting this right before writing any content is the most direct way to prevent keyword cannibalization later.